Example, example, example , and two visually identical Unicode strings that are not encoded the same way.
Choose the equality rule first
For identifiers, case may be significant. For email domains, it may not be. For human tags, leading/trailing spaces are often accidental. Decide whether comparison should be exact, trimmed, case-insensitive, or normalized before deleting anything.
Preserve a raw copy
Deduplication is destructive. Keep the source so you can audit how many entries disappeared and recover values if the normalization rule was too broad. This is especially important for imported customer data, access lists, or migration files.
First occurrence versus sorted output
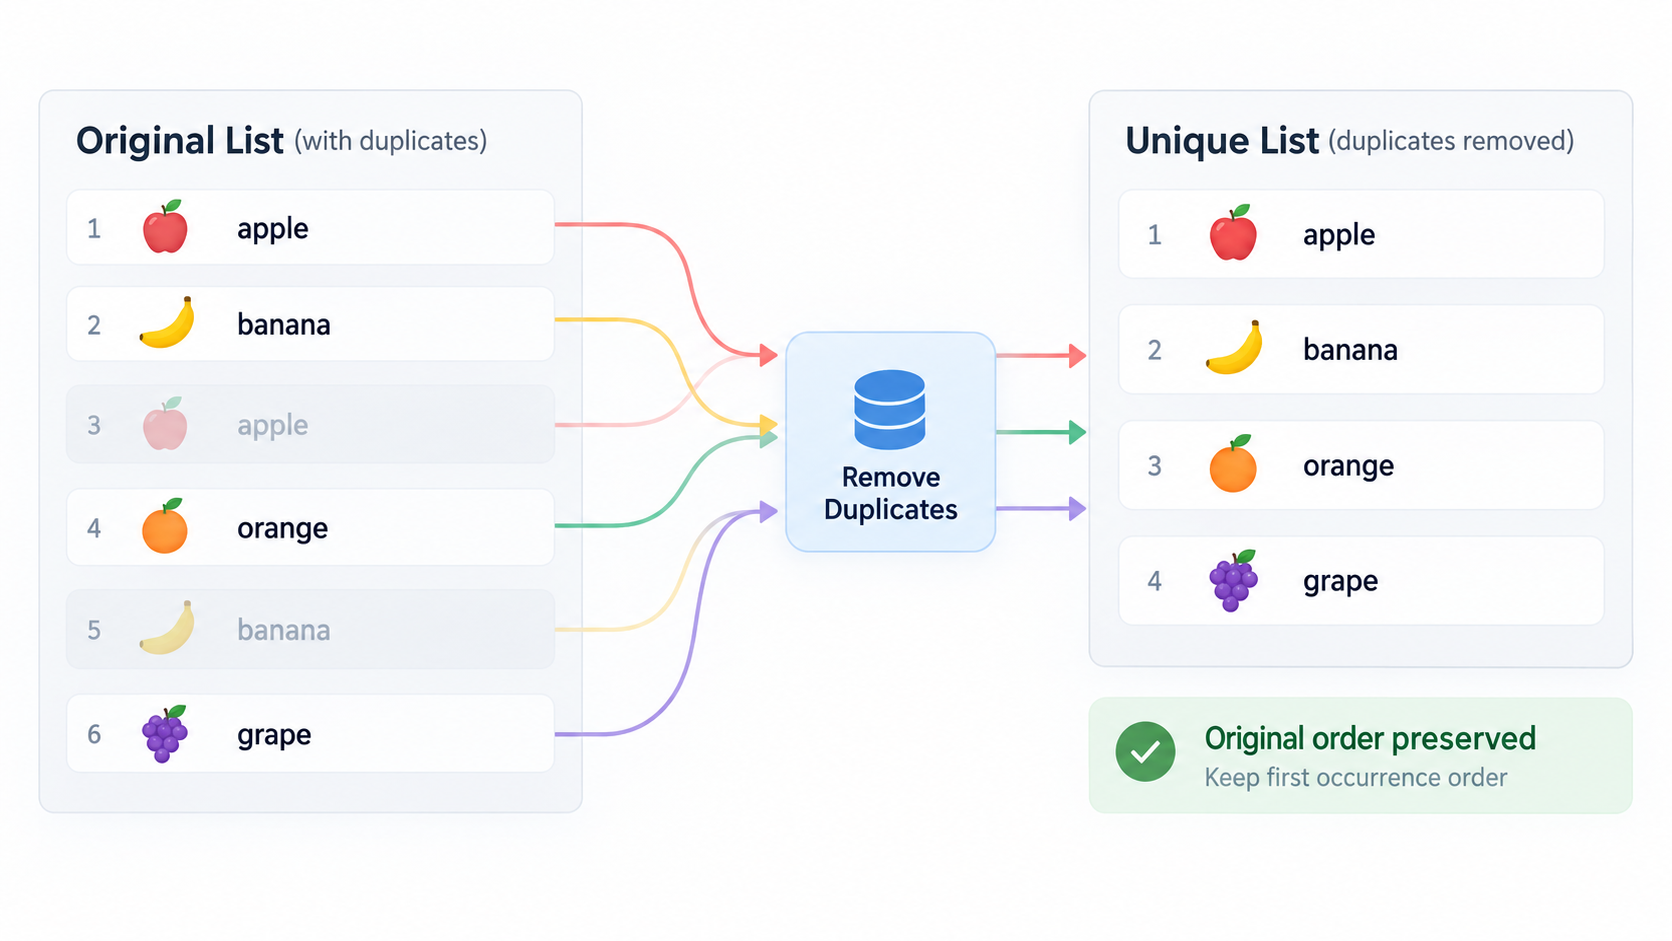
Many workflows keep the first occurrence and preserve original order. Others sort and then deduplicate. These produce different outputs. If sequence conveys priority or chronology, preserve order. If the list is a mathematical set, sorted output may be easier to review.
Whitespace can create invisible duplicates
alpha and alpha look identical in many editors. Clean known accidental whitespace with Whitespace Cleaner, then deduplicate a copy. Do not remove internal spaces when they distinguish legitimate values.
Case folding can merge distinct data
Case-insensitive matching might intentionally merge Admin and admin in a tag list, but it can be wrong for case-sensitive usernames, paths, API keys, or source code. Never apply a display-oriented normalization rule to opaque identifiers.
Review counts, not just output
If 10,000 input lines become 6,000 unique lines, that is useful information. A larger-than-expected reduction can reveal a broken export or overly aggressive normalization. Use Duplicate Line Remover on a sample first when the list is important.
FAQ
Can I deduplicate CSV by treating each row as a line?
Only for simple cases. CSV rows can contain embedded newlines and quoted values. Use a CSV-aware process when record structure matters.
Should blank lines be considered duplicates?
Usually repeated blank lines can be collapsed or removed for plain lists, but preserve them when they separate meaningful groups.
Practical next step
Use Duplicate Line Remover after you have written down the equality rule in plain language. If you cannot describe what “same” means, do not delete yet.